Open source CLI
Every picture lands on its word.
A markdown script and HTML slides in, a narrated mp4 out. Edit one line and only its section rebuilds.
Follows, DeckTalk's own film · 1:29 · Film and script
curl -LsSf https://decktalk.ai/install.sh | shNo API key, no sudo. Read it first.
Copied. Two more lines to a first film.
Measured
A cue waits for a word, not a second.
The voice times every word. Each picture names the phrase it waits for. A browser records the slides frame by frame.
- 7.8s
- to build a 50-second film from cold. 4.6 s after one word changes.
- The starter project with a click for each word in place of the voice, median of three on an Apple M5 Pro, Chromium and ffmpeg already fetched.
- 29ms
- the furthest any of Follows' 33 pictures landed from its word. Less than one frame. The median is 15 ms.
- Measured on the 30 fps film above by
decktalk verify, against the time the voice gave each word. - $0.02
- to voice the one changed line again after "Share" became "Send". The other line was kept. The first build, which voiced both lines, cost $0.03.
- The rebuild Follows shows (run 629b5a01): 60 characters at $0.30 per 1,000, as that build printed it.
Films
Three films, each with its script.
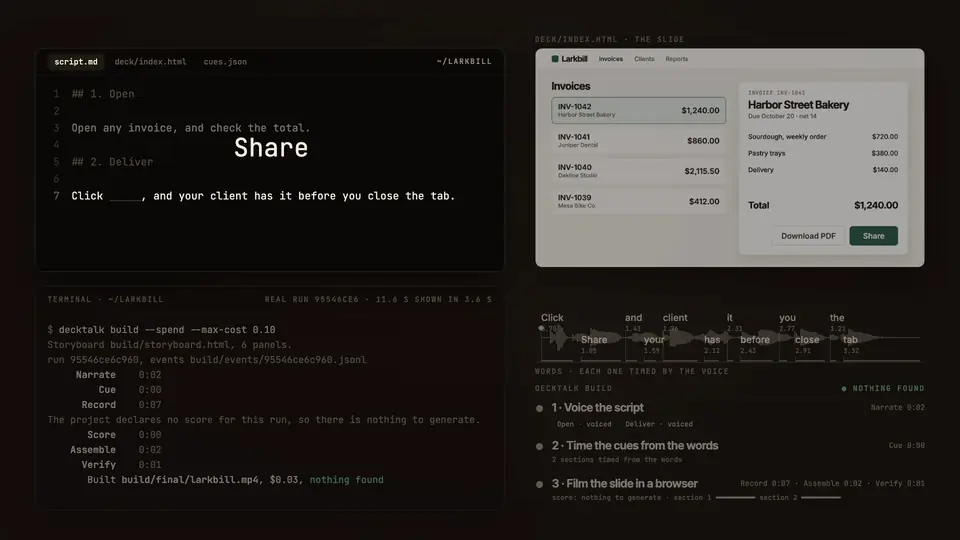 Follows
 uv, end to end
 Halfway
Asked first
What developers ask before they try it.
- Why not Remotion or Manim?
- They time a picture in frames or seconds, in code. DeckTalk times it from the spoken word, so a rewritten sentence moves its pictures with it, and the slides are your own HTML. For frame-by-frame animation, they are the better tools. The comparison, tool by tool.
- What is 29 ms measured against?
decktalk verifydecodes the finished mp4, finds the first frame where each picture changes, and subtracts the time the voice gave that word. A build with no voice is measured against the clicks in its own audio. How verify measures.- Is it tied to ElevenLabs?
- The voice is ElevenLabs today, a stock voice or a clone of your own. The script, the cues and the slides name no service, and what DeckTalk needs from any voice is a start and an end time for every word.
- Do I write JavaScript?
- No. A slide is HTML and CSS, and each thing that appears names its cue in a
data-inattribute. Headless Chromium records the page against the word times. - What comes out besides the mp4?
- Captions as SRT and VTT, chapters, a transcript page, a poster and every word's time as JSON, all built from the same word times. Every file.
- Can a coding agent run it?
- Yes. Every command prints JSON with
--json. Run without a terminal, a build with something to buy refuses unless--spendor--no-spendis passed, so an agent left alone cannot spend by accident.
Before you install
What it needs, and what it costs.
- Costs
- Free. The voice is your own ElevenLabs key, billed by ElevenLabs per character, and
decktalk build --no-spendbuilds the whole film for nothing, with a click on each word where the voice will be. The build asks before it spends, and--max-costrefuses a run that could cost more than you set. - Status
- Alpha The CLI and file formats still change between releases.
- Runs on
- macOS, and Linux with glibc. On Windows,
uv tool install decktalkfrom PowerShell. The installer brings its own Python through uv. - Downloads
- Chromium and ffmpeg on the first build, about 347 MB on a Mac with Apple silicon. It says so before it fetches them.
- Accounts
- None for DeckTalk. ElevenLabs is the one voice provider today.
- Licence
- Apache-2.0. Source, issues and changelog on GitHub.
Install
Three lines to a first film.
No account, no key, no Python to install first.
-
Installonce per machine
curl -LsSf https://decktalk.ai/install.sh | shInstalls uv, then DeckTalk. Never runs sudo. Read it first, or add
-s -- --dry-runaftershto see what it would do. Have uv already?uv tool install decktalk. Command not found? Open a new shell. -
Start a projectfor each film
decktalk init my-pitchWrites a script, its cues and a slide page that already build.
-
Buildafter every edit
cd my-pitch && decktalk build --no-spendWrites
build/final/my-pitch.mp4with a click on each word where the voice will be. No key.
After the first film
- Your own voice
- Put an ElevenLabs key in
.env(copy.env.example) and your voice id indecktalk.toml. The build asks before it spends. What a rebuild costs. - Two voices, motion, any shape
decktalk init --example interviewor--example motionwrites a finished project. One setting makes a film wide, square or vertical.- Coding agents
- Every project carries six skills in twelve files. An agent writes the files, reads the JSON every command prints, and fixes what it finds.
- Offline, CI and Linux
decktalk installfetches Chromium and ffmpeg ahead of time. On Linux it also installs Chromium's system libraries, the one step that asks for sudo.
Next: the quickstart, or how it works. Stuck? Open an issue.